DeceptionLessWrong
Another Slice of Swiss Cheese for Untrusted Monitoring
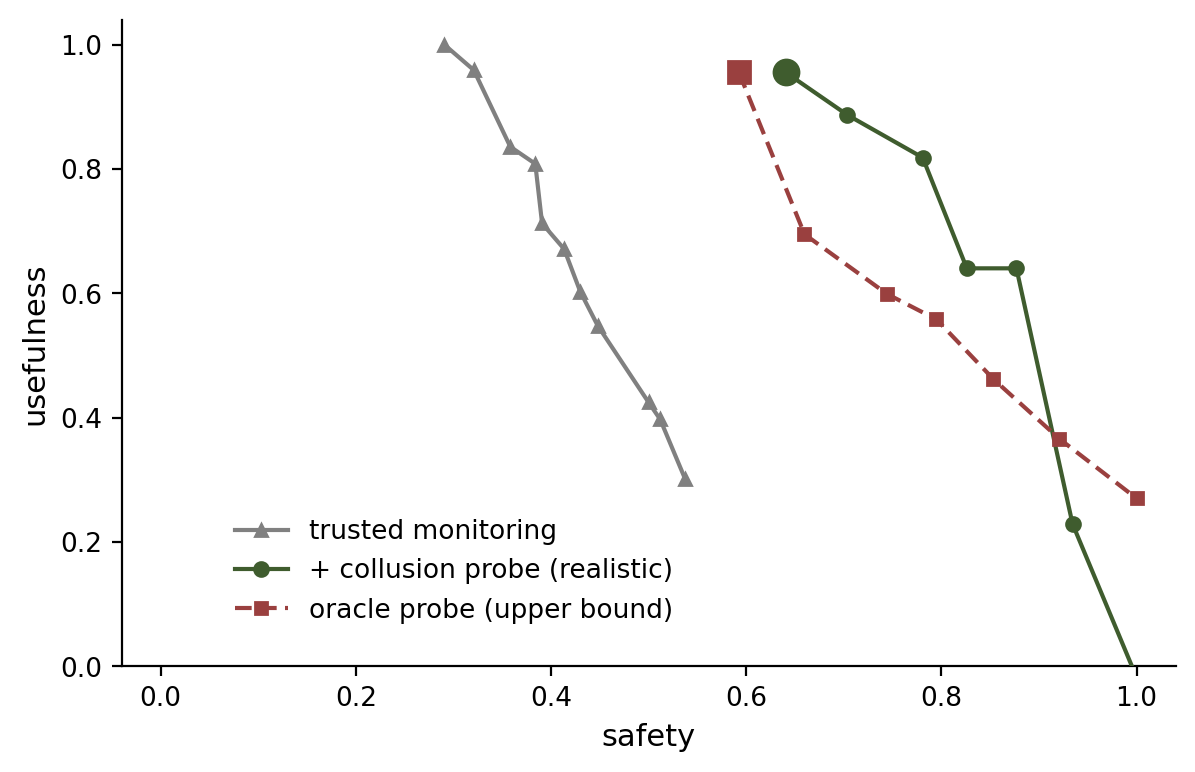
Catching the monitor in a lie by comparing what it perceives against what it reports. TL;DR I trained a linear probe to directly perceive code back-doors, which are represented linearly in activation space, using honest behaviour that can be elicited even from a scheming model. I then trained a...

